
Custom Queries integration
Updated
Introduction
The Custom Queries module allows you to create, run, and automate your own SQL queries within the data stored in your data warehouse — both data collected by WitCloud and data from external sources. This enables you to create custom views, reports, and datasets without modifying the main dataset structure.
Configuration guide
Follow the steps below to create the Custom Queries module.
Module configuration
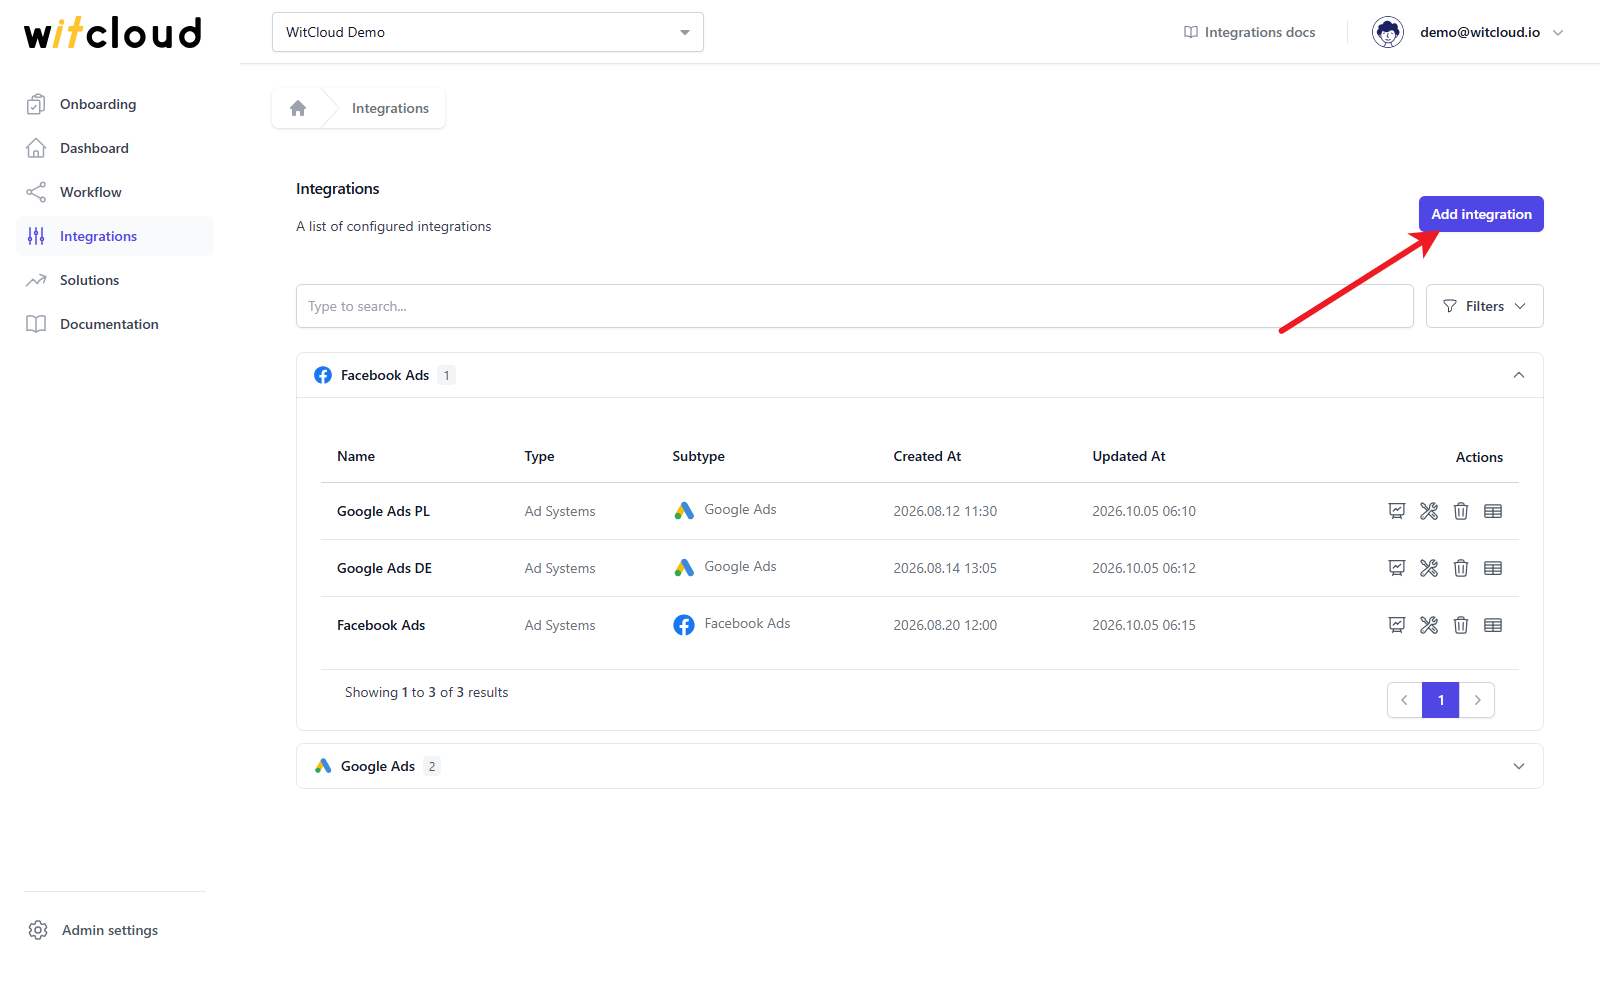
Go to Integrations in the menu and click Add integration.
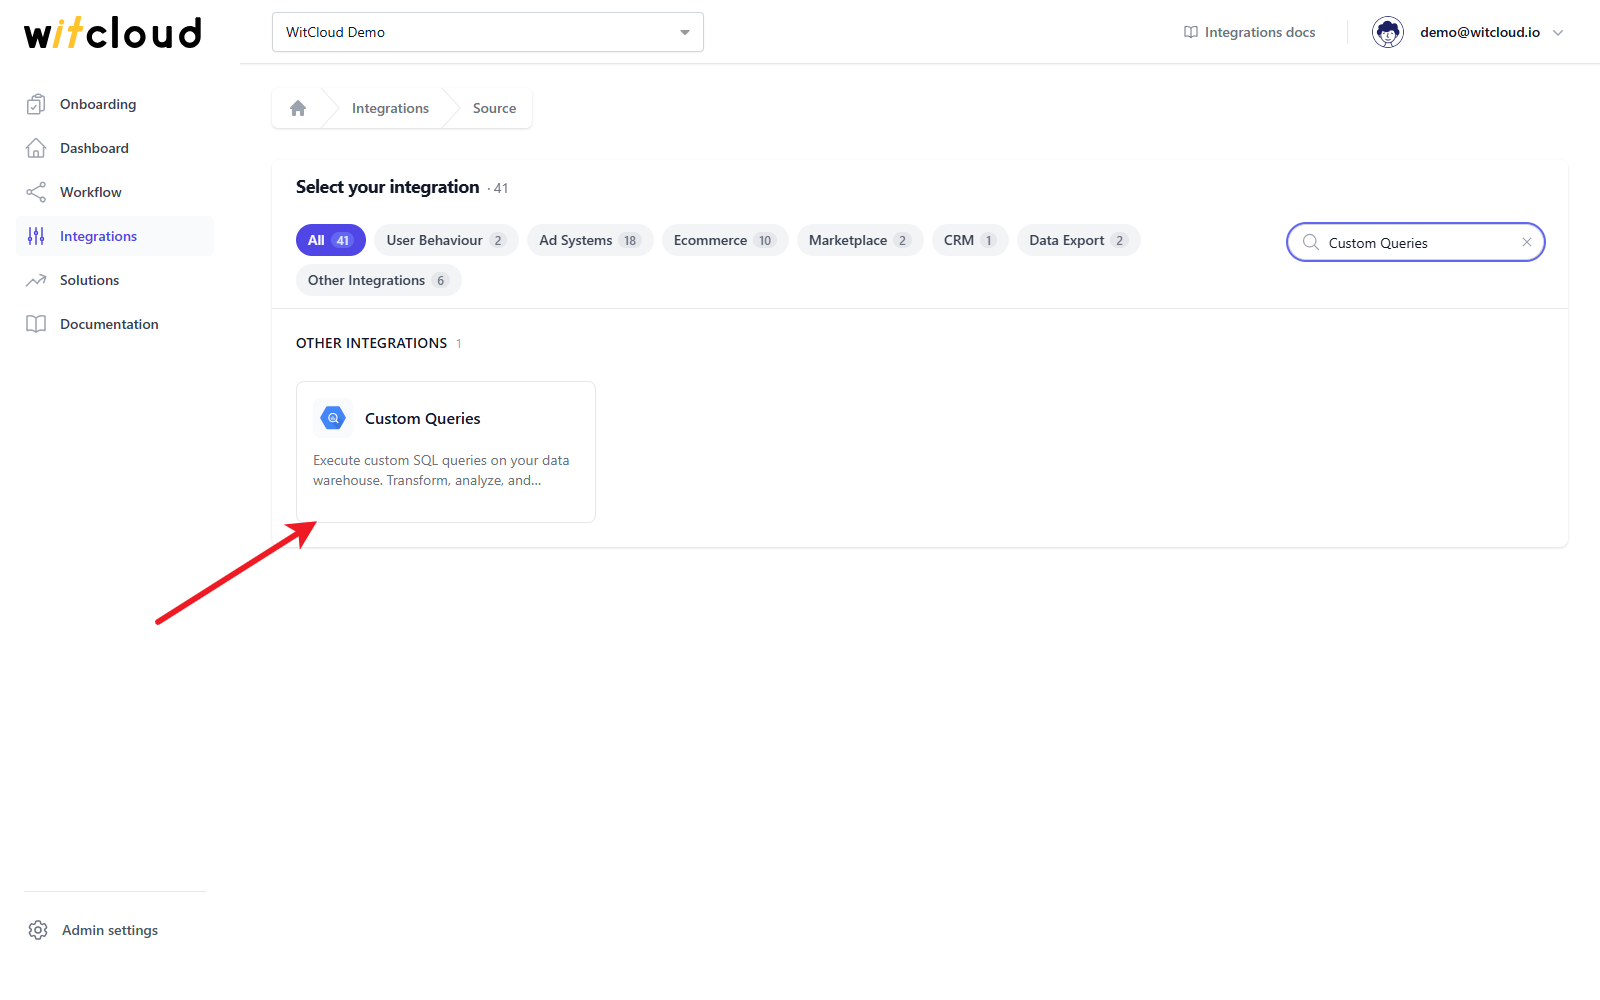
From the list of available integrations, select Custom Queries.
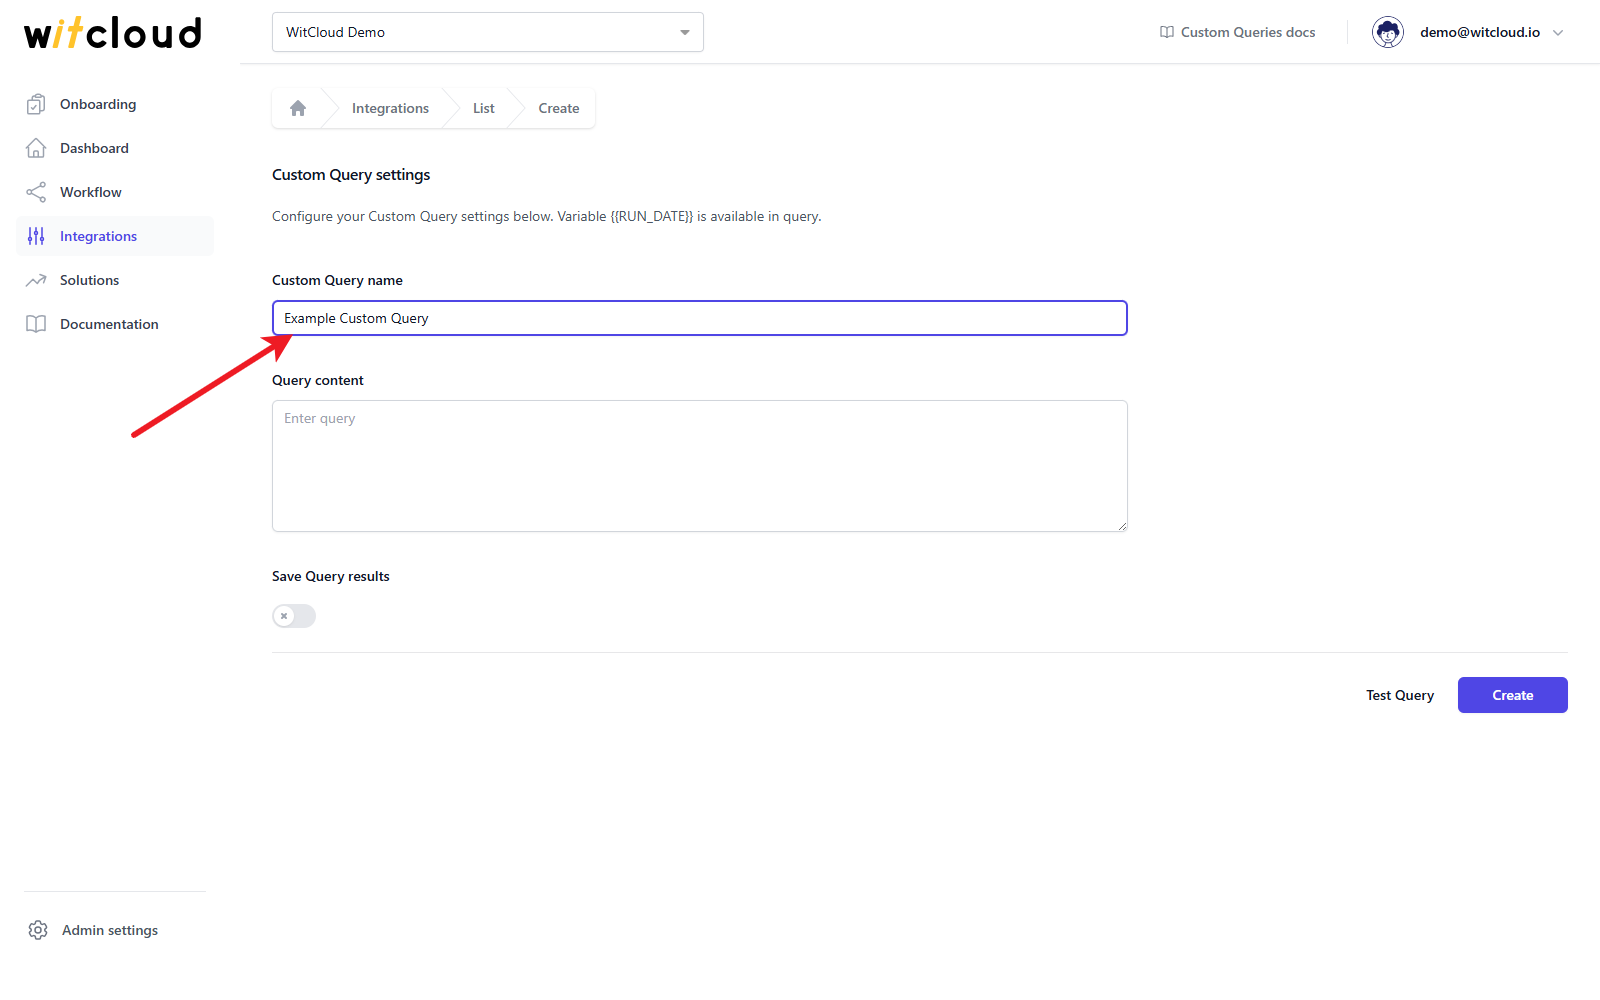
Enter the Custom Query name, e.g., "Example Custom Query".
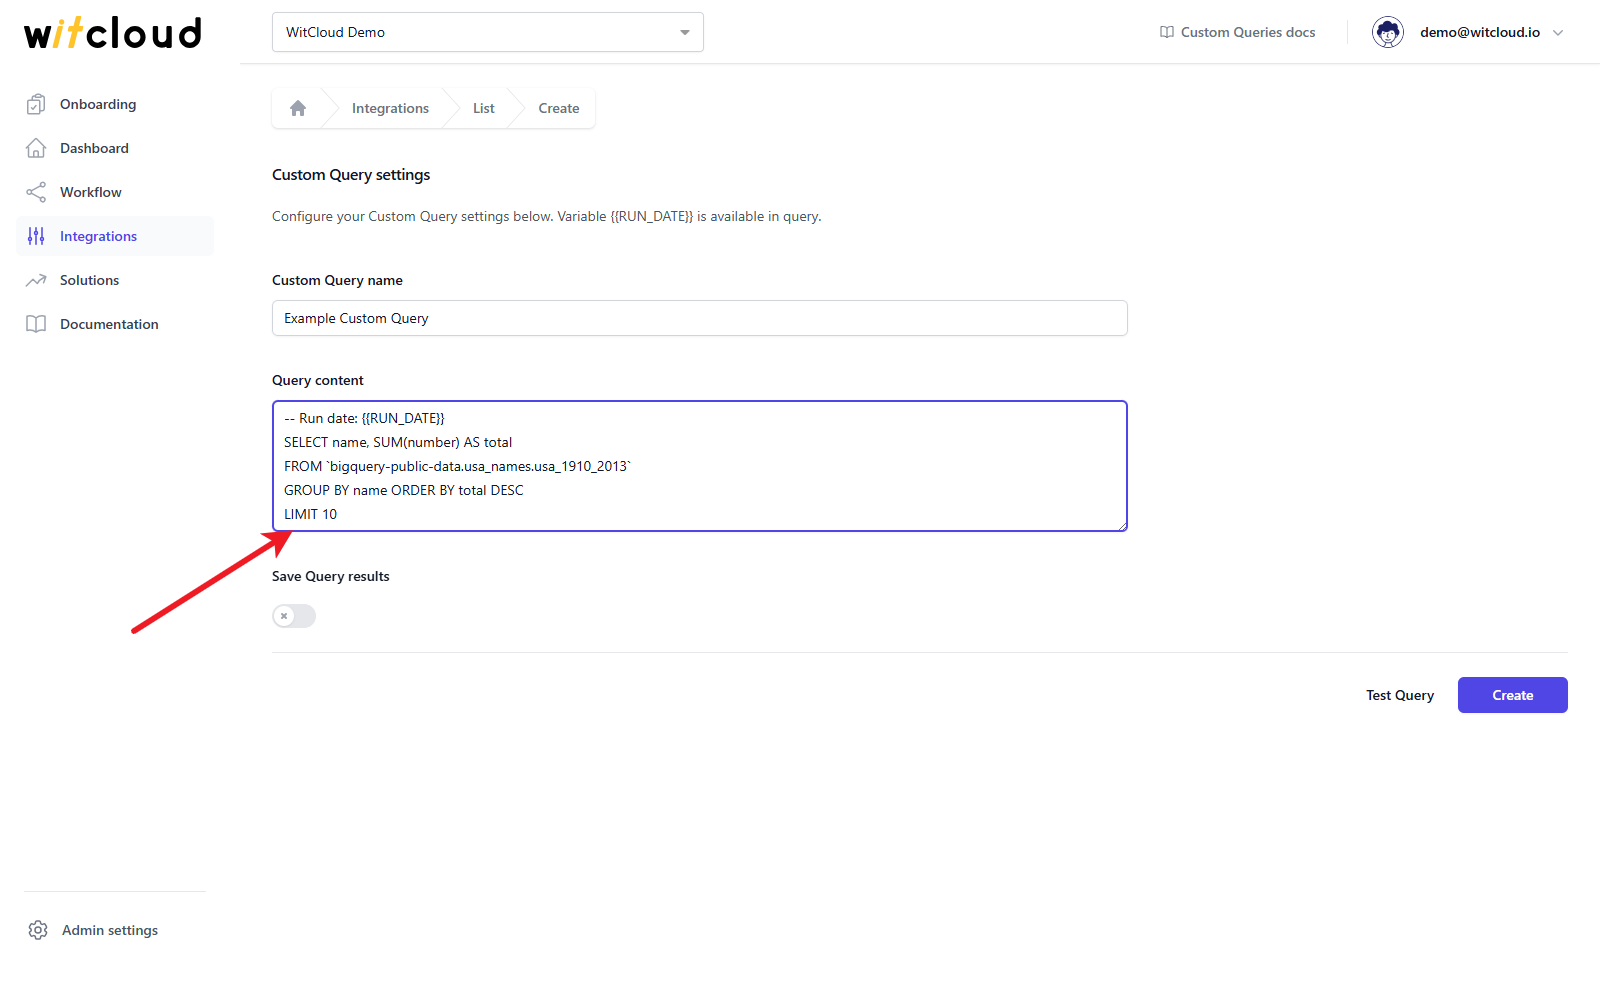
Enter the SQL query in the Query content field.
You can use the full BigQuery syntax and the {{RUN_DATE}} variable, which will automatically be replaced with the process execution date.
The {{RUN_DATE}} variable follows the YYYYMMDD format and corresponds to the scheduled task execution date or the manual run date.
Saving results
To save the query results in BigQuery, enable the Save Query results switch. Without it, the query is only run and nothing is written.
The Table settings section appears. In Destination table, enter the name of the table the results are written to. The default is results_{id}: {id} becomes the Custom Query's own id, so every query gets a table of its own. The name may contain only letters, digits and _, is written in lowercase, and the table is always in your project's dataset - the text above the field shows where the results go.
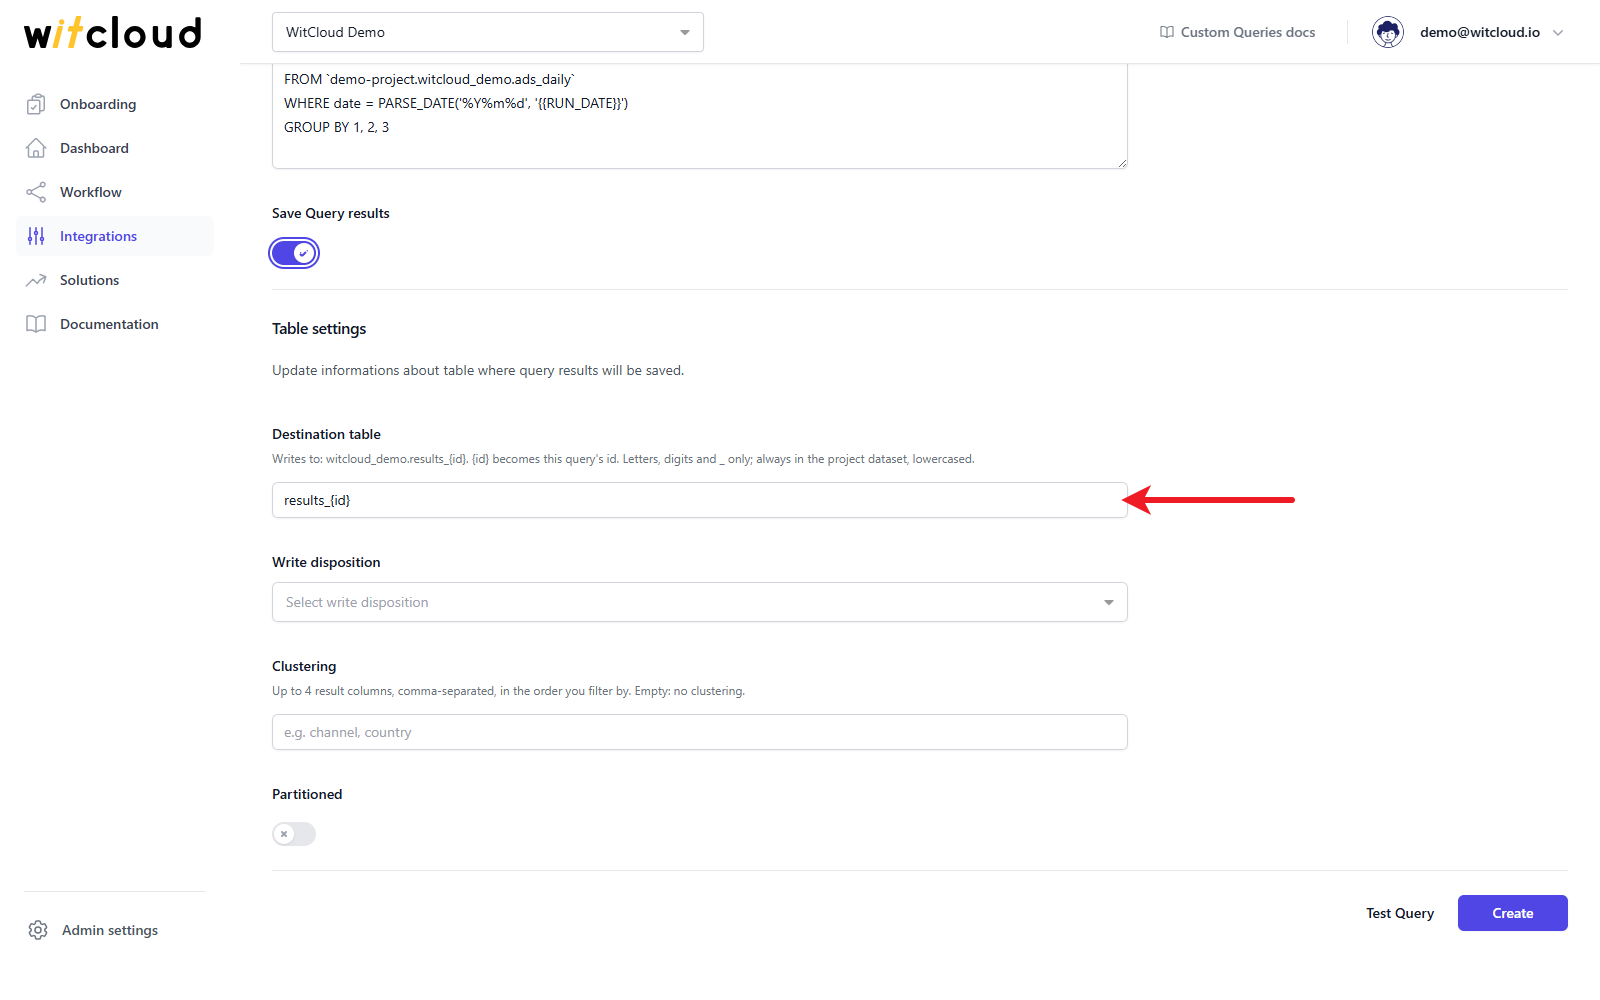
Two Custom Queries of a project cannot write to the same table.
Write disposition – the method of writing data:
- Overwrite if table/partition exists – replaces the table, or with partitioning by Ingestion time only the partition of the run's date.
- Append to table/partition – appends the results to the table.
- Write only if table/partition is empty – writes only if the table (or the run date's partition) is empty.
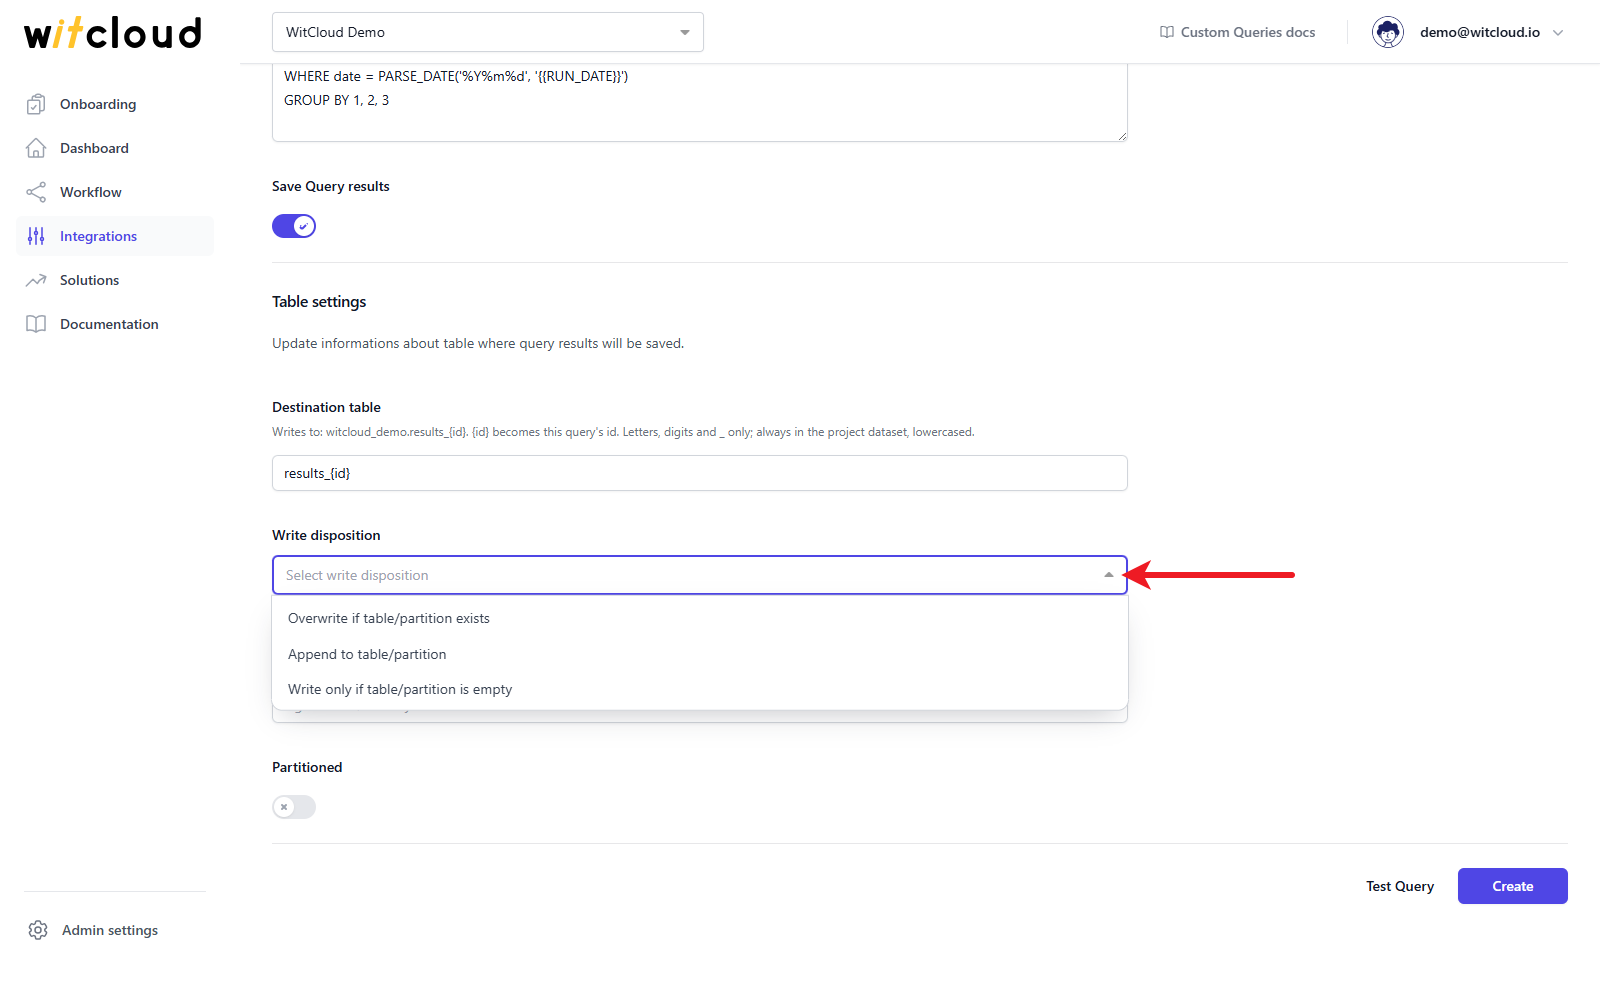
With Append to table/partition, or Overwrite if table/partition exists on a table partitioned by Ingestion time, columns you add to the query are added to the table automatically.
Clustering
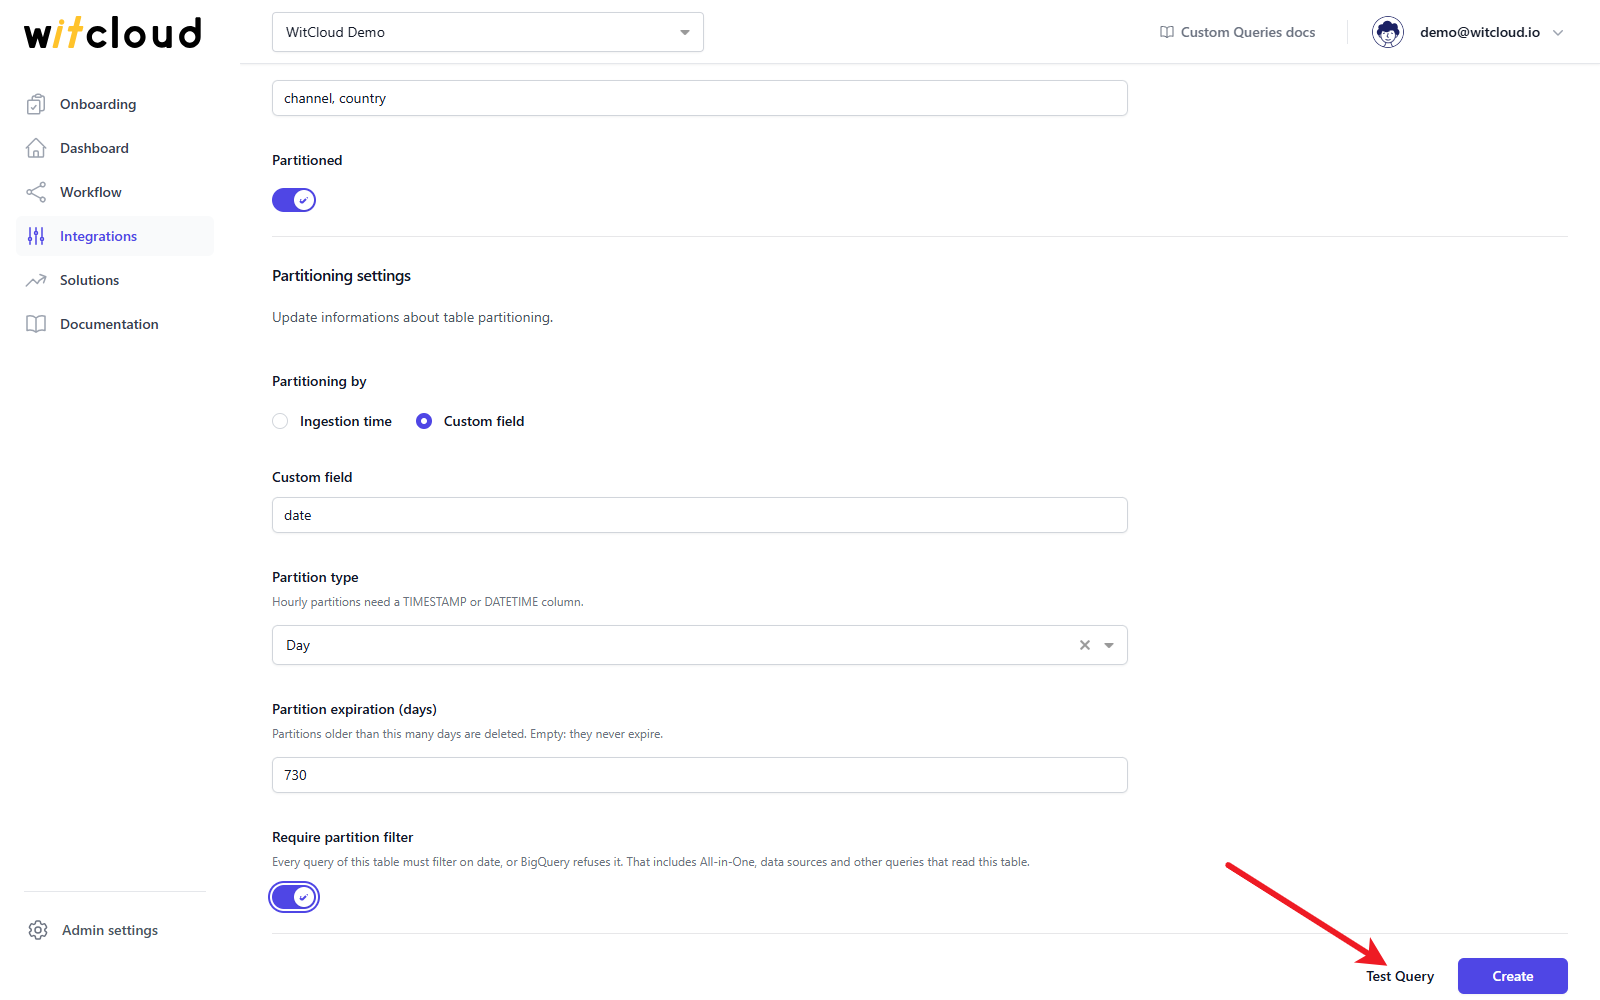
Clustering orders the stored data by up to 4 of the query's result columns. Enter the column names separated by commas, in the order you filter by most, e.g. channel, country. Leave it empty for no clustering.
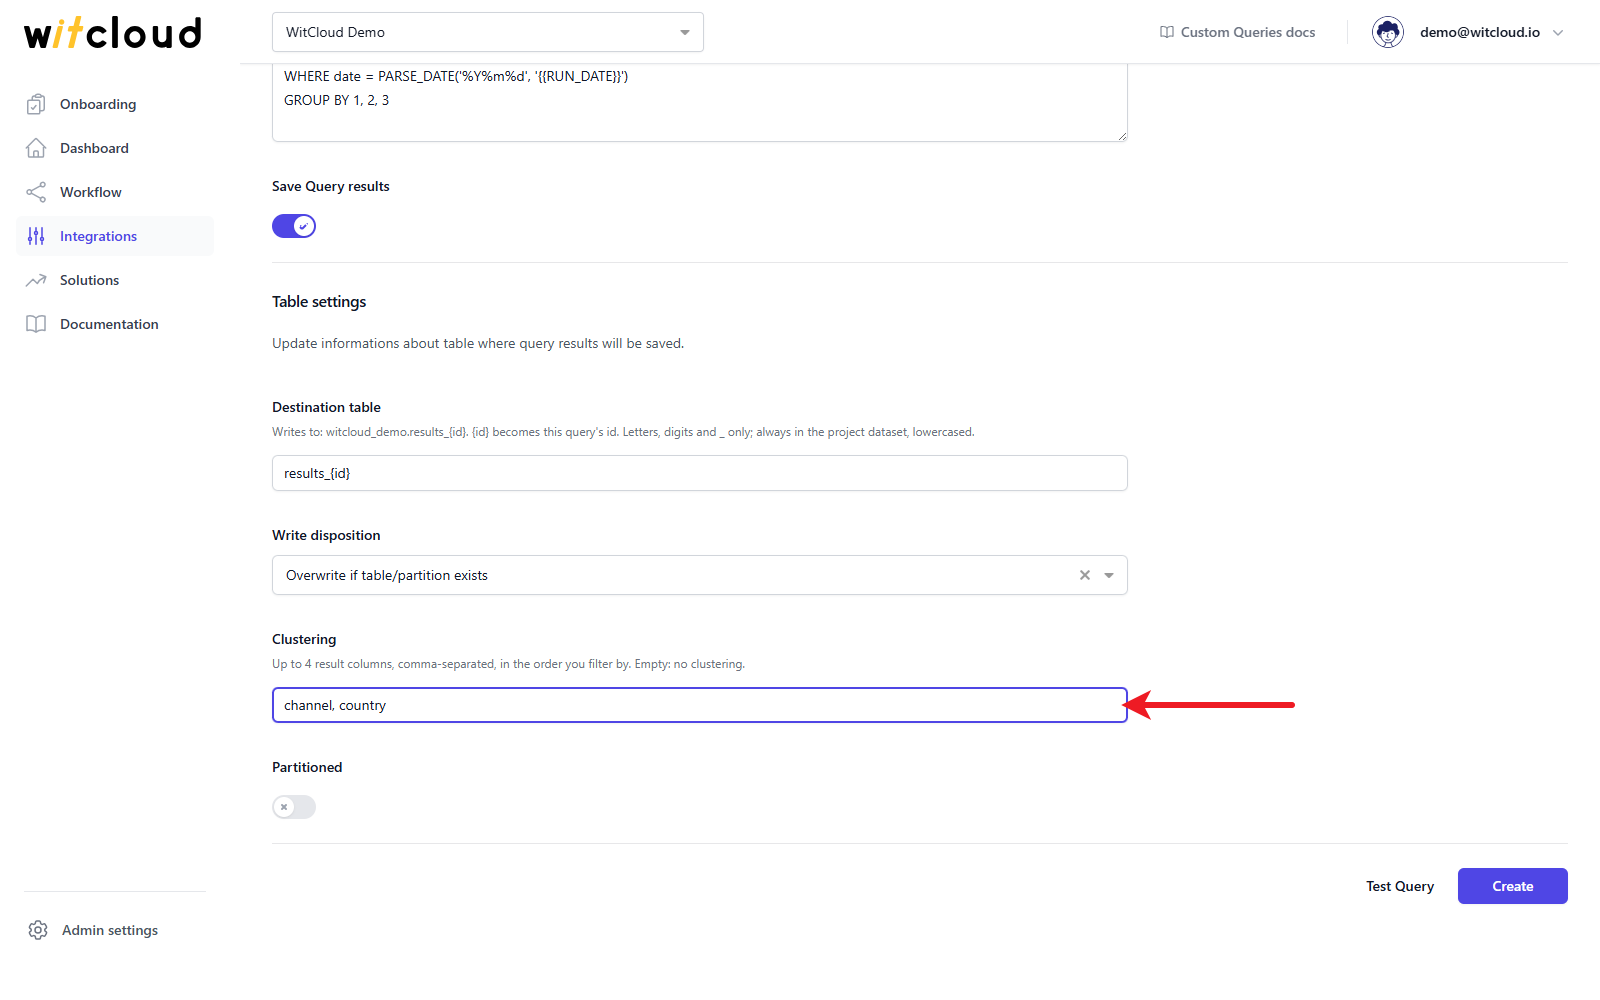
The columns must be among the query's result columns and of a type BigQuery can cluster on, and cannot repeat. When you change the clustering of a query whose table already exists, the table is changed with the next run.
Data partitioning
If you want the results to be saved in a partitioned table, enable the Partitioned option. The Partitioning settings section appears:
- Partitioning by:
- Ingestion time – each run writes the partition of its own date.
- Custom field – partitions by a column of the query's results. Enter its name in the Custom field box; the column must be
DATE,TIMESTAMPorDATETIME.
- Partition type – Day, Month or Year, and Hour with a Custom field of type
TIMESTAMPorDATETIME. The default is Day. - Partition expiration (days) – partitions older than this many days are deleted. Leave it empty to keep them forever.
- Require partition filter – every query of this table must filter on the partitioning column (
_PARTITIONTIMEwith Ingestion time), or BigQuery refuses it. That includes All in One, data sources and other queries that read this table, so switch it on only when they all filter on it.
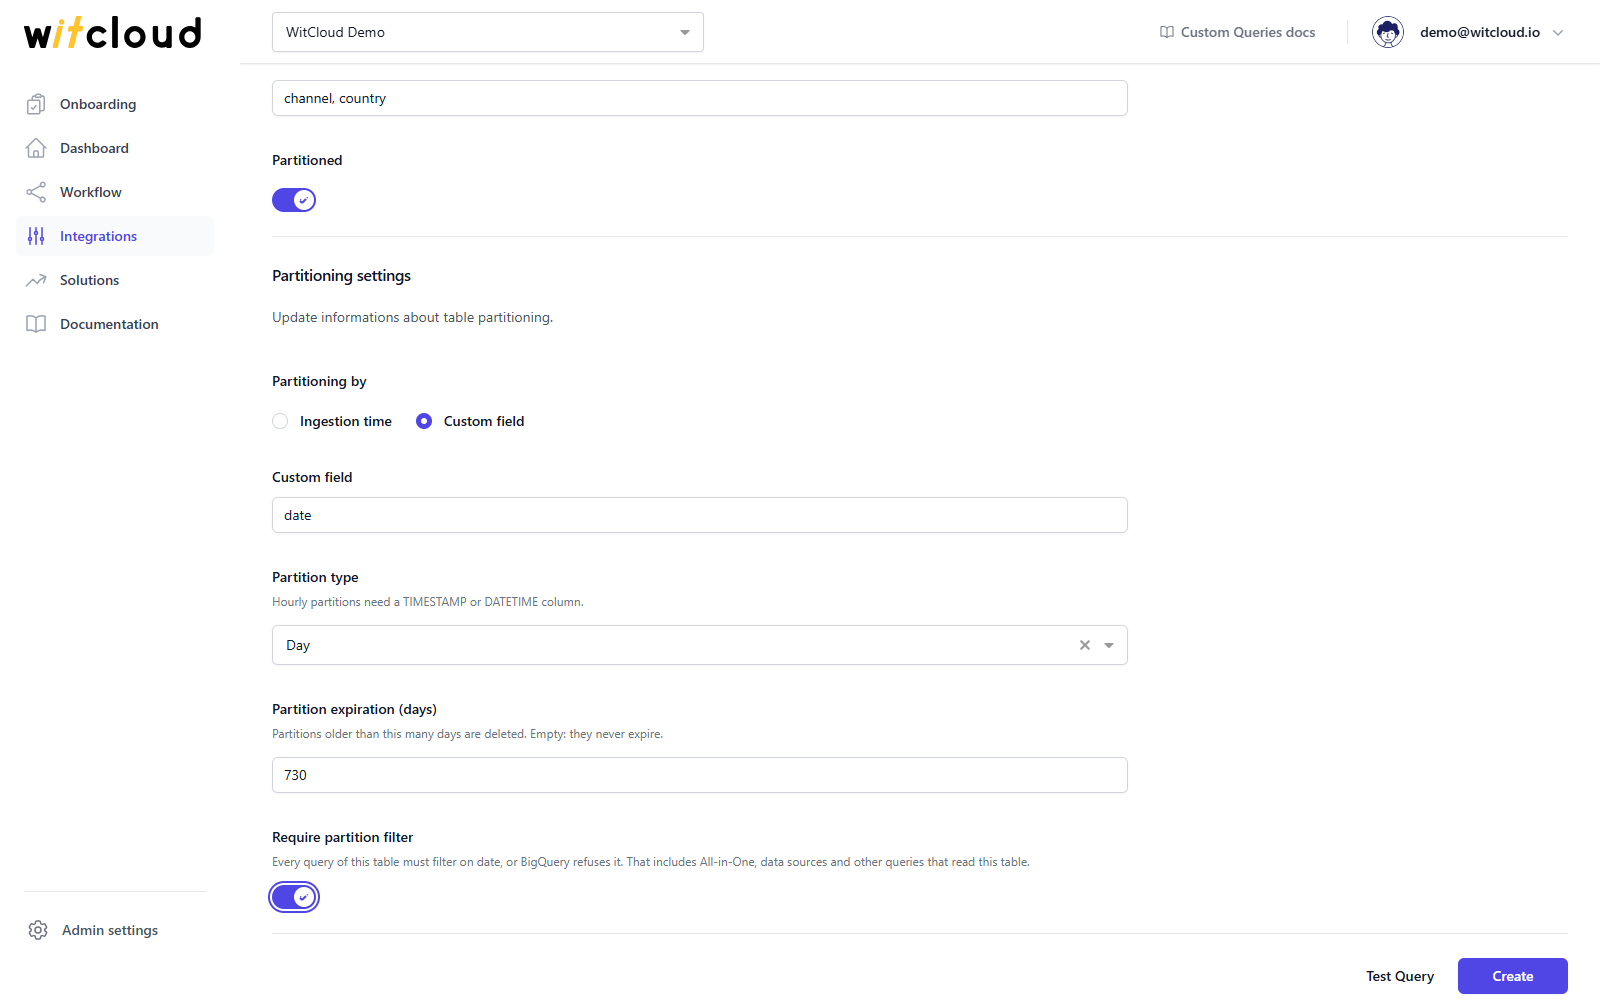
This allows you to easily manage large datasets and speed up processing in BigQuery.
Query testing
Before saving the configuration, click Test Query.
This runs a dry run of the query, which costs nothing and writes no data. {{RUN_DATE}} is replaced with yesterday's date. The test also checks the Table settings against the columns the query returns.
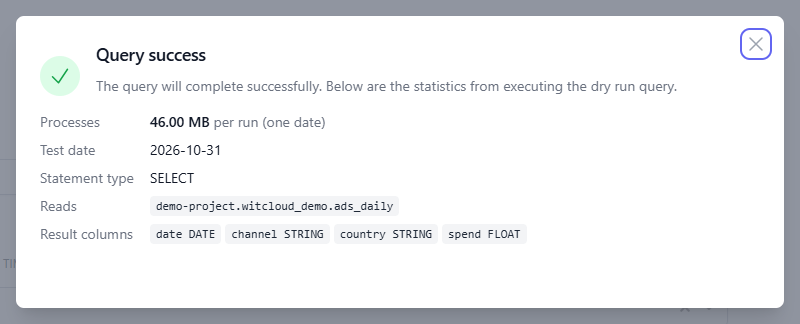
If the query is correct, the Query success window shows how much data one run processes (Processes ... per run), the Test date, the Statement type, the tables it Reads and its Result columns.
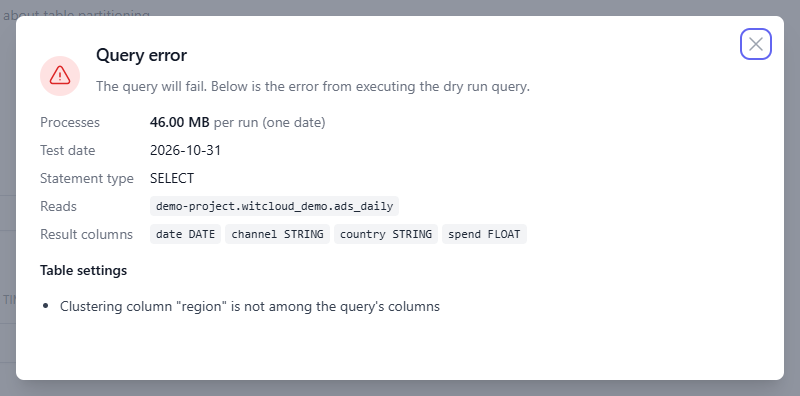
Otherwise the Query error window shows the error from BigQuery, or under Table settings what in the table settings does not fit the query (see Troubleshooting).
Click Create to save the module. Create runs the same test first: if it finds a problem, nothing is saved and the Not saved: fix the query window shows what to fix.
Done! The Custom Query module has appeared on the Integrations list and is now ready to use.
Remember that the table will appear only after the module is run in the Workflow!
To change a Custom Query later, open it from the Integrations list, change the settings and click Save. Save runs the test too.
Execution and scheduling
To run the module and set up its schedule, you need to configure a Workflow. You can read more about it here.
Troubleshooting
The test and Create/Save can report these problems with the table settings:
- The table name cannot contain a dot: results always go to the project dataset. – enter the table name without a dataset.
- The table name may contain only letters, digits and _. / The only placeholder a table name takes is {id}. – remove the other characters from Destination table.
- Clustering takes at most 4 columns. / Clustering columns cannot repeat. – shorten the Clustering list.
Clustering column "…" is not among the query's columns/Partitioning column "…" is not among the query's columns– the column is missing from the query's results; check its name in Result columns.Partitioning column "…" is STRING; it must be DATE, TIMESTAMP, DATETIME– partition by a date or time column, or convert the column in the query.Query job "…" already writes to …; choose another destinationTable– another Custom Query of the project writes to this table; choose another Destination table.